Autopilot
The self-improving half of Preflight. Preflight decides whether the SO-101 robot should act; Autopilot learns from what fails. Each cycle reads the served GR00T N1.7 policy's benchmark, finds the generalisation axis (new objects, tasks or environments) with the most failures a tested recipe could fix, trains it, and lets a paired gate decide. Nemotron on Nebius Token Factory proposes; it never scores its own result.
1. Diagnosefailures by axis and mode, from the served policy's benchmark
Reads the served policy's result files (8 suites x 96 paired rehearsals), puts each suite on an axis (objects, tasks, environments, or seen scenes as the guard) and counts failures by mode: no_contact, pushed, dropped, holding, fell_off. It also reads the learning requests intake filed from Preflight's refusals.
So far 5 learning requests filed from Preflight's refusals, 4 picked up by a cycle.
2. Proposerank a fixed menu of tested recipes; Nemotron picks one of the top three
Five tested recipes are ranked by failed rehearsals each could win back per GPU hour. Recipes that answer a Preflight refusal rank first; a closed family stays out unless a refusal reopens it. The top three eligible go to Nemotron 3 Ultra on Nebius Token Factory, which picks one and says what result would count as success. A choice off the list falls back to the ranking.
So far 7 cycles planned - cycle 1: task_round:basket (human); cycle 2: task_round:ring (nemotron); cycle 3: dagger_round (nemotron); cycle 4: dagger_round (nemotron); cycle 5: real_cotrain (ranking); cycle 6: failure_synthesis (nemotron); cycle 7: failure_synthesis (nemotron).
3. Traindetached on the A100, gated on free GPU memory, heartbeat every 30 min
The chosen script starts detached (PPID 1) behind autoresearch-wait, which holds until 70 GB of GPU memory and 20 GB of RAM have stayed free for two minutes, so other jobs on the host are never displaced. A heartbeat checks in every 30 minutes and flags a run whose log has stopped growing.
So far 7 runs finished, nothing running.
4. Benchmarkthe same 96 paired scenes per suite, seed 42
The candidate rehearses exactly the scenes the reference did: 12 scenes x 8 perturbations per suite at seed 42. Every rehearsal therefore pairs with the reference's on the identical scene, which is what makes the gate paired.
So far 3 candidates benchmarked on the same 576 paired rehearsals as the served policy.
5. Gate (G3)paired gain on the target suites, no suite worse
McNemar's test on the scenes where the two policies disagree. The target suites pooled must be better and no suite anywhere significantly worse (p < 0.05); a gain on the suite a recipe trains on directly doesn't count. The verdict (PROMOTE, KEEP or DISCARD) goes into the cycle log and verdicts.yaml.
So far 3 judged: 3 DISCARD. Closed families: best-of-n, flux3, multitask, synthesis, v6, v7.
6. Humanapproves promotion; the new policy becomes the next reference
Only npai autopilot approve promotes a candidate. Until then Preflight keeps serving the current policy and the next cycle plans against the same reference, so nothing the agent does reaches the robot unreviewed.
So far 0 promotions approved, so the policy Preflight serves is still the one a human last signed off.
Architecture: the agentic loop
An agent proposes; code decides. The only free choice the agent makes is which tested recipe runs next; everything that could flatter a result (the benchmark, the gate, promotion) is outside its reach.
flowchart LR
  subgraph HF["Hugging Face Spaces"]
    PF["Preflight
perception + trust gate"]
  end
  subgraph A100["GPU host (A100)"]
    IN["intake
refusals to requests"]
    PL["planner
rank the menu"]
    RUN["runner
wait for GPU, train, heartbeat"]
    BM["benchmark
MuJoCo twin + GR00T, 96 paired / suite"]
    G3{"gate G3
paired McNemar"}
  end
  subgraph TF["Nebius Token Factory"]
    NM["Nemotron 3 Ultra
chooses 1 of top 3"]
  end
  LED[("verdicts.yaml
closed families")]
  HU(["human
approves promotion"])
  PF -->|"RETRY / ASK_HUMAN"| IN --> PL
  BM -->|"served policy's failures"| PL
  LED --> PL
  PL -->|"eligible recipes"| NM -->|"choice + rationale"| PL
  PL --> RUN --> BM --> G3
  G3 -->|pass| HU -->|new served policy| PF
  G3 -->|"DISCARD / KEEP"| LED
  classDef hf fill:#12141c,stroke:#f2c14e,stroke-width:2px,color:#f3f4f6
  classDef gpu fill:#12141c,stroke:#00ffaa,stroke-width:2px,color:#f3f4f6
  classDef tf fill:#12141c,stroke:#a497ec,stroke-width:2px,color:#f3f4f6
  classDef gate fill:#12141c,stroke:#ff6b5e,stroke-width:2px,color:#f3f4f6
  classDef human fill:#12141c,stroke:#9aa1b1,stroke-width:2px,color:#f3f4f6
  classDef mem fill:#12141c,stroke:#8ab4ff,stroke-width:2px,color:#f3f4f6
  class PF hf
  class IN,PL,RUN,BM gpu
  class NM tf
  class G3 gate
  class HU human
  class LED mem
  style HF fill:transparent,stroke:#f2c14e
  style A100 fill:transparent,stroke:#00ffaa
  style TF fill:transparent,stroke:#a497ec
Preflight
Rehearses the robot's policy in a twin of the scene; files every scene it won't clear.Intake
Sorts each refusal into the axis training could fix, or marks it unmet (perception).npai autopilot intake
Planner
Ranks 5 tested recipes by failures they could win back per GPU hour; refusals first; closed families out.npai autopilot plan
Nemotron 3 Ultra
Chooses one of the top three and says what would count as success.Runner
Launches detached, waits for free GPU memory, checks in every 30 min.Benchmark + gate G3
Same 96 scenes per suite at seed 42; paired gain on the target suites, no suite worse. The worked example below opens with this card.Human
Approves promotion; the new policy becomes Preflight's and the next reference.npai autopilot approve
Memory
Every event incycles.jsonl; verdicts in verdicts.yaml, which closes
families until a new refusal reopens them. How the gate decides: paired McNemar
Paired: the old and new policy run the same 96 scenes per suite (seed 42: same objects, same camera jitter), so they are compared scene by scene, not just as two totals.
| new succeeds | new fails | |
|---|---|---|
| old succeeds | no information | new lost it |
| old fails | new won it | no information |
Only scenes where they disagree count. If the new policy were no better, those would split like coin flips; the p-value says how unlikely the actual split is under that. A suite moves only at p < 0.05.
Cycle 1, read through the gate
| suite | won / lost | p | reads as |
|---|---|---|---|
| basket (trained) | +82 / −2 | <0.001 | real gain |
| ring (held out) | +0 / −0 | 1.0 | no change: no transfer |
| clean_many | +2 / −14 | 0.004 | real loss |
| real_1_pomade_tin | +2 / −21 | <0.001 | real loss |
| held_out_objects | +9 / −19 | 0.087 | leans worse, within noise |
G3 asks two things: the target suites pooled are better (paired), and no suite anywhere is worse. A suite the recipe trains on directly doesn't count as a gain (basket), so cycle 1 had no target gain and two losses: DISCARD. With only 96 rehearsals, comparing totals (57 vs 61) can't tell luck from progress; pairing cancels each scene's difficulty, so small real differences show and luck doesn't count as a win.
Where the policy fails now
The reference the latest cycle was planned against: 96 paired rehearsals per suite in the randomised twin. New tasks are the gap; seen scenes are the guard.
What the loop is targeting
Requests from Preflight
Every scene Preflight would not clear
is filed here as a learning request (npai autopilot intake). Recipes that answer one rank first. A refusal
caused by an untrustworthy twin is a perception problem: it is recorded as unmet, not turned into training.
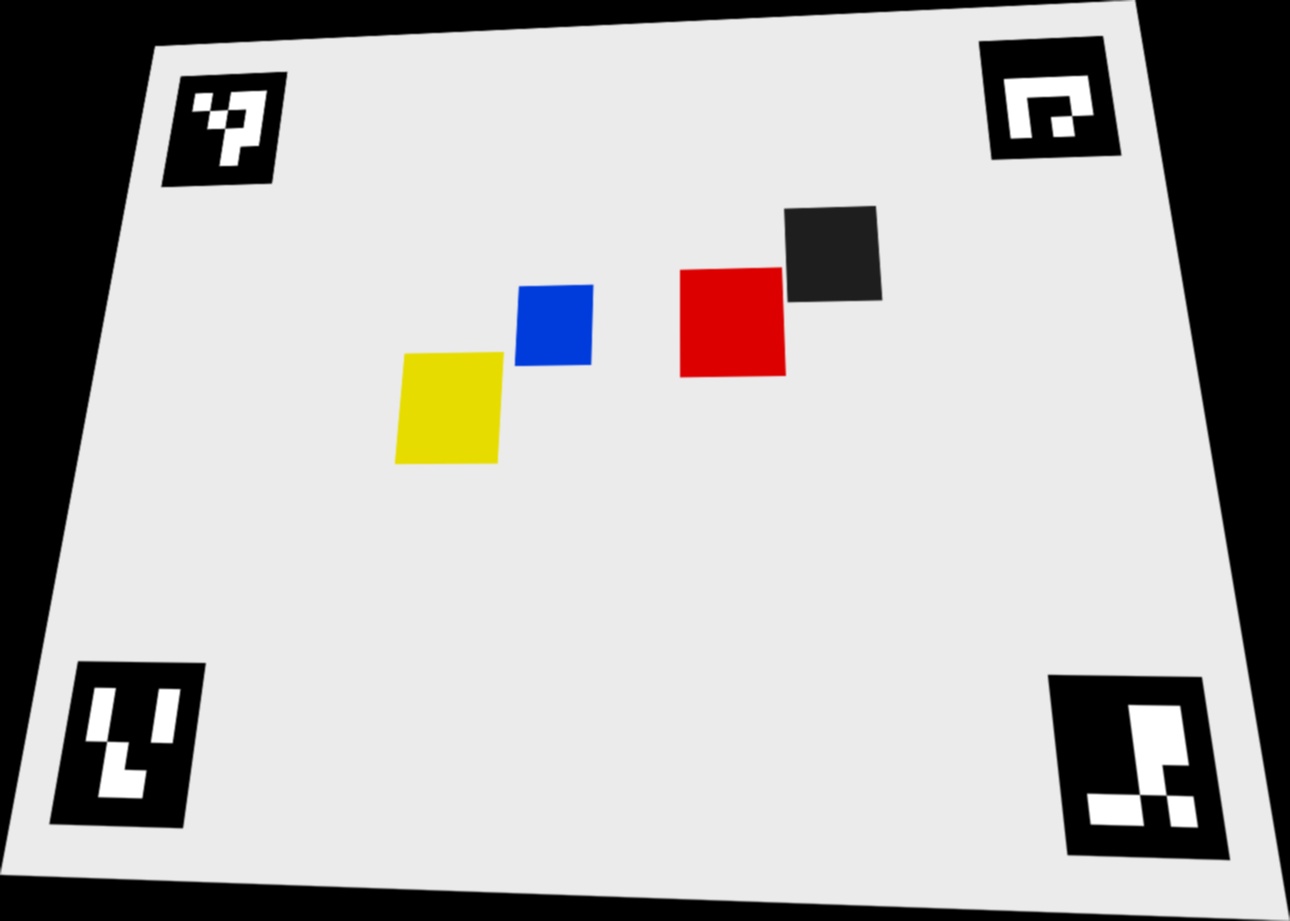
cluttered ASK_HUMAN
no twin was built (no blue block on the mat; the marker view shows ['yellow', 'red']); recognising the objects fixes that, not policy training.
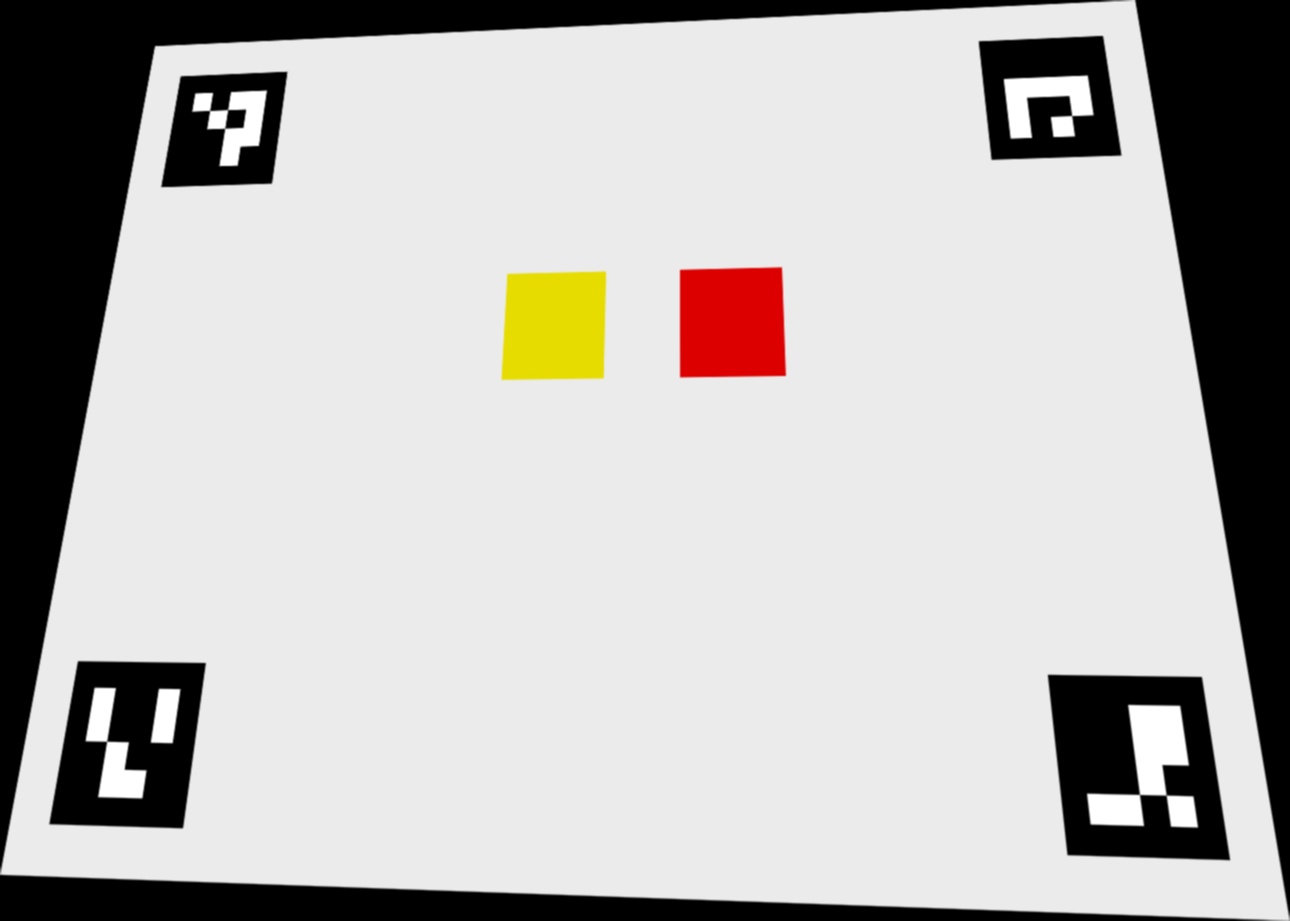
new task RETRY
asked 'Pick yellow and place on red', outside the one task it was trained on.

real photo ASK_HUMAN
asked 'Pick yellow and place on red', outside the one task it was trained on; a twin was built from the photo, but its perception scores 0.24, below 0.60 (extra yellow object at (301, 155) mm treated as a distractor; vision model did not confirm the yellow block at (70, 146) mm), so a rehearsal on it isn't trusted; better recognition or measured object models fix that, not policy training.
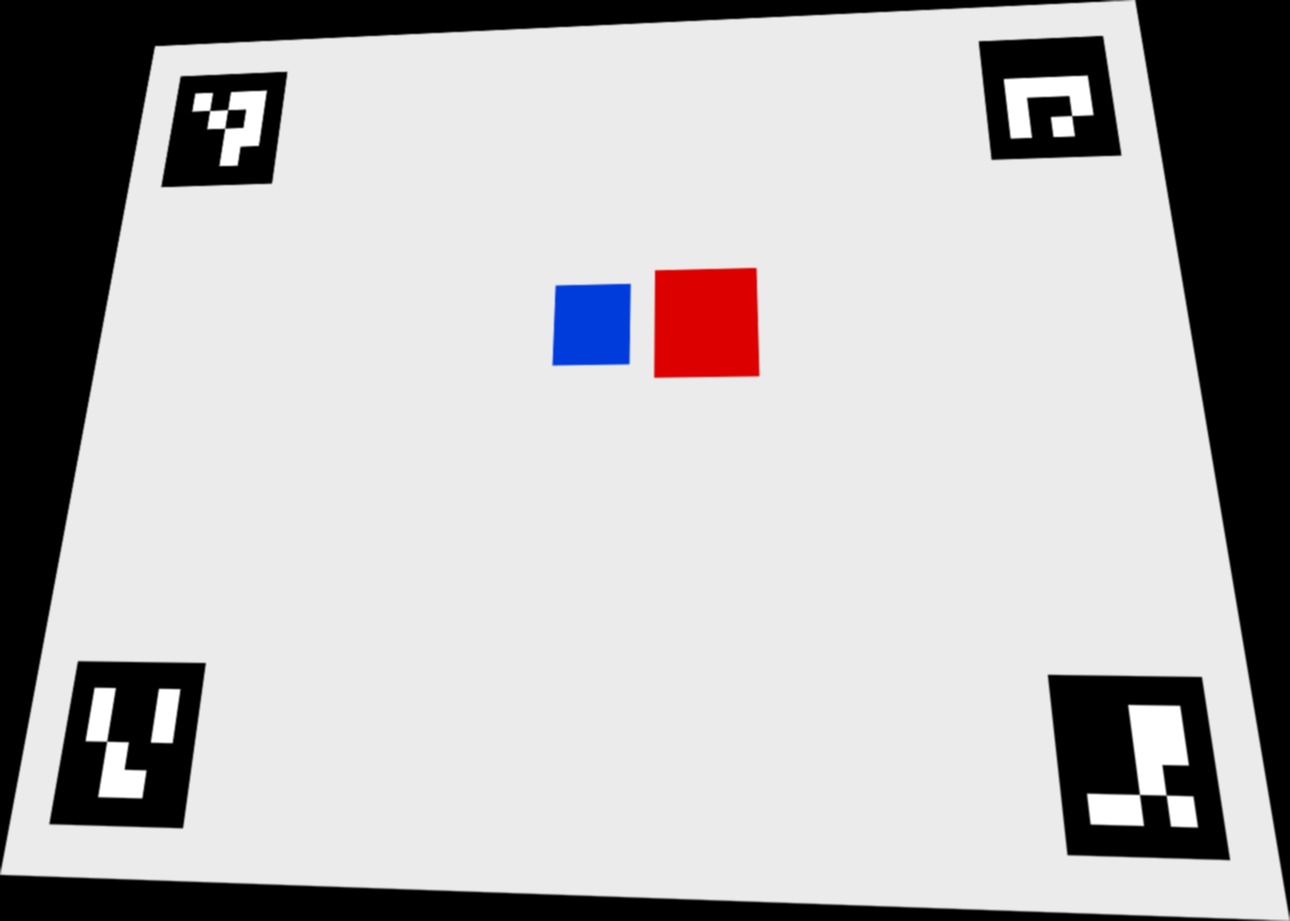
tight gap RETRY
only 25 of 32 rehearsals succeeded in this layout.
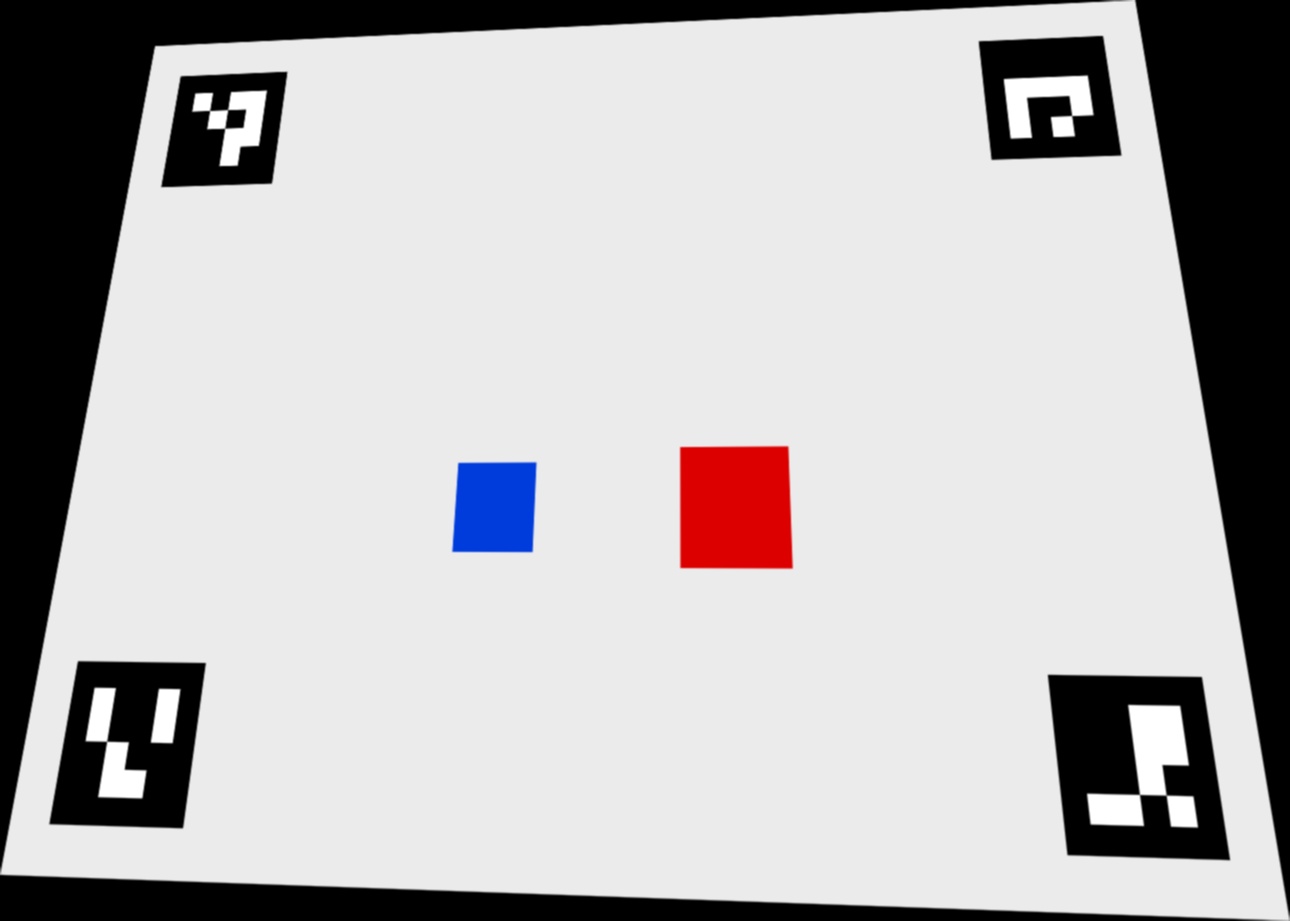
too close RETRY
only 1 of 32 rehearsals succeeded in this layout.
Cycles
Cycle 7: failure_synthesis FAILED
This action targets the object-axis failures (dropped, holding, pushed) that dominate the held_out_objects suite (57/96) and block the new_task and real_photo requests, which require generalising to unseen tasks and tolerating perception noise rather than the recovery behaviours that previously closed the synthesis family. Success means raising held_out_objects above 57/96 with no regression on any other suite.
Cycle 6: failure_synthesis FAILED
This reopened synthesis action targets the object-axis failures (dropped, holding, pushed) that appear in held_out_objects (57/96) and directly answers the new_task and real_photo requests where the policy fails on unseen task specifications. Success means raising held_out_objects above 57/96 with paired gains and no regression on any other suite, addressing the generalization gap that the original synthesis closure (unnecessary recoveries) did not.
Cycle 5: real_cotrain DISCARD
NEBIUS_API_KEY not set; the top-ranked candidate (Nemotron not asked). real_cotrain could win back up to 24 failed rehearsals.
Judged: worse on clean_many, real_1_pomade_tin_many, in_path_pomade_tin_many
- held out objects: 57/96 -> 50/96 (52%) within noise (+6/-13, p=0.167)
- seen vocabulary: 78/96 -> 75/96 (78%) within noise (+6/-9, p=0.607)
- clean many: 88/96 -> 64/96 (67%) worse (+2/-26, p=0.000)
- clean top down many: 85/96 -> 79/96 (82%) within noise (+3/-9, p=0.146)
- real 1 pomade tin many: 87/96 -> 62/96 (65%) worse (+1/-26, p=0.000)
- in path pomade tin many: 88/96 -> 79/96 (82%) worse (+3/-12, p=0.035)
Cycle 4: dagger_round DISCARD
dagger_round targets the dominant failure modes in objects (dropped 11, pushed 8, holding 6) and environments (pushed 15, holding 5, dropped 3) while addressing four refused requests across both object and environment axes, including the new-task generalisation gaps (new_task, real_photo). It is judged on the three environment suites plus the weak held_out_objects suite (57/96), so paired gains there with no regressions would confirm the fix.
Judged: worse on real_1_pomade_tin_many, in_path_pomade_tin_many
- held out objects: 57/96 -> 59/96 (61%) within noise (+11/-9, p=0.824)
- seen vocabulary: 78/96 -> 76/96 (79%) within noise (+5/-7, p=0.774)
- clean many: 88/96 -> 88/96 (92%) within noise (+3/-3, p=1.000)
- clean top down many: 85/96 -> 82/96 (85%) within noise (+3/-6, p=0.508)
- real 1 pomade tin many: 87/96 -> 77/96 (80%) worse (+2/-12, p=0.013)
- in path pomade tin many: 88/96 -> 79/96 (82%) worse (+4/-13, p=0.049)
Cycle 3: dagger_round DROPPED
The tasks axis is catastrophically weak (6/192 successes) with 177 no_contact failures on held-out tasks, indicating a fundamental generalization gap to new tasks. dagger_round uniquely answers "new_task" and targets environment/object gaps that manifest as dropped/holding/pushed errors, offering the highest reach (48) per GPU hour. Success would be measured by non-trivial gains on held_out_task_basket and held_out_task_ring suites.
Dropped: rationale misread what dagger_round is judged on; prompt fixed to give each recipe its judged suites
Cycle 2: task_round:ring DROPPED
The tasks axis is catastrophically failing at 6/192 successes, with 177/186 failures being 'no_contact' — the policy cannot even initiate contact on held-out tasks. The ring suite shows 0/96 successes, making it the hardest generalization gap. A successful result would be achieving first-contact and sustained manipulation on the ring task, lifting its suite from 0% to >50% success.
Dropped: cycle 1 showed a task round learns only the trained task (basket 6->86, ring 0->0) and costs stacking; four Preflight refusals now wait
Cycle 1: task_round:basket DISCARD
Started by hand on 17 Oct, before the loop existed: train on basket and hold out ring, so a ring gain measures task transfer.
Judged: worse on clean_many, real_1_pomade_tin_many
- held out objects: 57/96 -> 47/96 (49%) within noise (+9/-19, p=0.087)
- seen vocabulary: 78/96 -> 81/96 (84%) within noise (+5/-2, p=0.453)
- clean many: 88/96 -> 76/96 (79%) worse (+2/-14, p=0.004)
- clean top down many: 85/96 -> 87/96 (91%) within noise (+5/-3, p=0.727)
- real 1 pomade tin many: 87/96 -> 68/96 (71%) worse (+2/-21, p=0.000)
- in path pomade tin many: 88/96 -> 82/96 (85%) within noise (+3/-9, p=0.146)
- held out task basket: 6/96 -> 86/96 (90%) better (+82/-2, p=0.000)
- held out task ring: 0/96 -> 0/96 (0%) within noise (+0/-0, p=1.000)
The menu, ranked
Reach: failed rehearsals on a recipe's axes that fail the way it addresses. Nemotron chooses among the top three eligible; families every past attempt of which was discarded are closed.
| recipe | reach | GPU h | reach / h | status |
|---|---|---|---|---|
| failure_synthesis | 25 | 6 | 4.2 | reopened, closed by: 437/576; worse on held_out_objects (43), clean_many (76) and real_1_pomade_tin_many (75). Synthesised states teach recoveries the policy does not need. |
| dagger_round | 48 | 6 | 8.0 | already judged against this reference |
| real_cotrain | 24 | 6 | 4.0 | already judged against this reference |
| task_round:basket | 186 | 5 | 37.2 | family 'multitask' closed in verdicts.yaml |
| task_round:ring | 186 | 5 | 37.2 | family 'multitask' closed in verdicts.yaml |
Rules the loop can't break
- One change per cycle, so every gain is attributable.
- A fixed menu of tested scripts; the agent can't write or run anything else.
- The gate is code (paired McNemar on the same scenes), not the agent. G3 counts gains on suites the recipe did not train on, and fails if any suite gets worse.
- Closed families (best-of-n, flux3, multitask, synthesis, v6, v7) are reopened only for refusals they were never tried on, rank after open recipes, and Nemotron is shown what closed them.
- Promotion needs a human. GPU use waits for free memory, so other jobs on the host are never displaced.
Every experiment so far
| experiment | verdict | result |
|---|---|---|
| v5 fine-tune (800 scripted twin demos) | PROMOTE | 438/576 pooled; held_out_objects 52/96; so101-benchmark 0/50. Reference for every later comparison. |
| v6 targeted demos (staged-mistake recoveries, lookalike decoys) | DISCARD | 421/576, within noise on every suite. |
| v7 visual domain randomisation (textured floors, Seeed wrist mount) | DISCARD | wrist-mount scenes 15 -> 53, but clean_many 81 -> 58; so101-benchmark 1/50. |
| DAgger round 1 (recoveries 3.5% of training) | KEEP | 436/576; recoveries too diluted to move anything. |
| DAgger round 2 (recoveries x8, about a third of training) | PROMOTE | 464/576, no suite worse; real_1_pomade_tin 86 vs 74 (+14/-2, p=0.004). Served until round 3 was promoted. |
| DAgger round 3, first run (harvested with round 2) | KEEP | 481/576, pooled gain within noise; held_out_objects 61 vs 50 (+18/-7, p=0.043), the first significant gain on new objects. Checkpoint deleted on KEEP; retrained below. |
| DAgger round 3, retrained from the kept recoveries | PROMOTE | 483/576, pooled better (+19), no suite worse; held_out_objects 57 vs 50 (p=0.30; first run 61). The pooled gain replicates (481 then 483). Served policy. |
| DAgger round 4, residual RL expert recording recoveries | KEEP | harvest 614/800; RL expert recovered 88 of 120 kept states (73%, vs the script's 40%); 304 recoveries x8 in training. 471/576 (-12, within noise); held_out_objects 49 vs 57 (p=0.17); no_contact rose 18 to 39. |
| DAgger round 5, RL-expert recoveries weighted x2 | DISCARD | harvest 610/800; RL expert recovered 72 of 113 (64%); 160 RL recoveries x2 + 216 scripted x8. 455/576; held_out_objects 41 vs 57 (p=0.004, worse). Lower weight did not help; the RL-recovery line is closed. |
| FLUX 3 Action LoRA, trained fairly (same demos, same sample volume) | DISCARD | 50/576, worse on every suite (p<0.001); so101-benchmark 0/7. Open-loop error 2.71 vs 8.24 for holding the pose at 32 steps. |
| FLUX 16-step chunks | DISCARD | held_out_objects 4 vs 3 (p=1.0); clean_many 2 vs 9 (worse, p=0.039). |
| Best-of-8 chunk consensus on round 2 | DISCARD | held_out_objects 55 (+14/-9, p=0.41); clean_many 87 (p=1.0). Within noise at 8x inference cost. |
| DiVeR verifier best-of-8 on round 3 | DISCARD | verifier trained on 300 round-3 rollouts (226 succeeded) reaches held-out step AUC 0.79, but picking with it scores held_out_objects 54 (+12/-9, p=0.66) and clean_many 85 (+6/-3, p=0.51). Best-of-N selection is closed. |
| RL expert, residual PPO on the scripted expert | KEEP | held-out snapshot recovery 74.0% vs the expert's 45.9% at 3.0M steps (61.6% at 500k); stopped 11 Oct to free CPU, best checkpoint kept, fresh scenes 100%. Clears its bar; next step is recording its recoveries as DAgger data. |
| RL expert, shaped PPO from scratch (grasp reward) | DISCARD | held-out recovery 6% at 6.2M steps (training success 41%, fresh scenes 73%). Stopped 11 Oct for missing the bar. |
| Real-data co-training v9 (400 ArmnetBench teleop demos, 23% of samples) | DISCARD | 373/576 vs v5 438; held_out_objects 48 vs 52 (p=0.59); worse on clean_many (62 vs 81, p=0.001), clean_top_down_many (69 vs 83, p=0.001), real_1_pomade_tin (62 vs 74, p=0.043); so101-benchmark 0/50. Failures mostly pushed (84 of 203) and knocked_place (21). |
| Calibrated co-training v11 (block-stacking real episodes, joint offsets fitted to the twin, 9% of samples) | KEEP | calibrate fits offsets of -6.0, -6.0, -5.1 (LeRobot units) on shoulder lift, elbow flex and wrist flex, cutting real frames under the twin's table from 99.7% to 4.2%. Round 3 fine-tuned 4k steps at lr 1e-5 with 87 block-stacking episodes (50 teleop, 37 successful rollouts) at 9% of samples - 472/576 vs 483, every suite within noise (lowest p=0.18, held_out_objects 57 vs 57). Calibrated real data no longer costs the twin anything (v9 lost 65); whether it helps on the real arm is untested. v10, the workspace filter tried first, kept 11 of 400 demos and was superseded. |
| Failure-state synthesis (expert recoveries from jittered failure states, round 6) | DISCARD | 437/576; worse on held_out_objects (43), clean_many (76) and real_1_pomade_tin_many (75). Synthesised states teach recoveries the policy does not need. |
| Autopilot cycle 1: multi-task round, basket trained, ring held out (400 demos, 5 phrasings) | DISCARD | basket 6 -> 86/96 (+82/-2), the trained task learnt; ring 0 -> 0/96, no transfer to the held-out task. Stacking paid for it - clean_many 88 -> 76 (p=0.004), real_1_pomade_tin 87 -> 68 (p<0.001), the rest within noise. |
| Autopilot cycle 4: DAgger round 7, chosen by Nemotron to answer four Preflight refusals | DISCARD | 461/576. 800 rollouts, 123 failure states kept, 32 recovered (26%); held_out_objects 59 (+11/-9, within noise) but real_1_pomade_tin 87 -> 77 (p=0.013) and in_path_pomade_tin 88 -> 79 (p=0.049) worse. DAgger is near saturation on these failure modes. |